Project Info
Client
Fintech, Legal & Global Supply Chain Enterprises
Service
Multi-Modal Document Parsing & Vision AI
Industry
Financial Services, Legal, Logistics
Stack
Vision-LLMs, LayoutLMv3, Tesseract OCR, Python FastAPI, PostgreSQL, AWS Textract, Docker
The Business Challenge
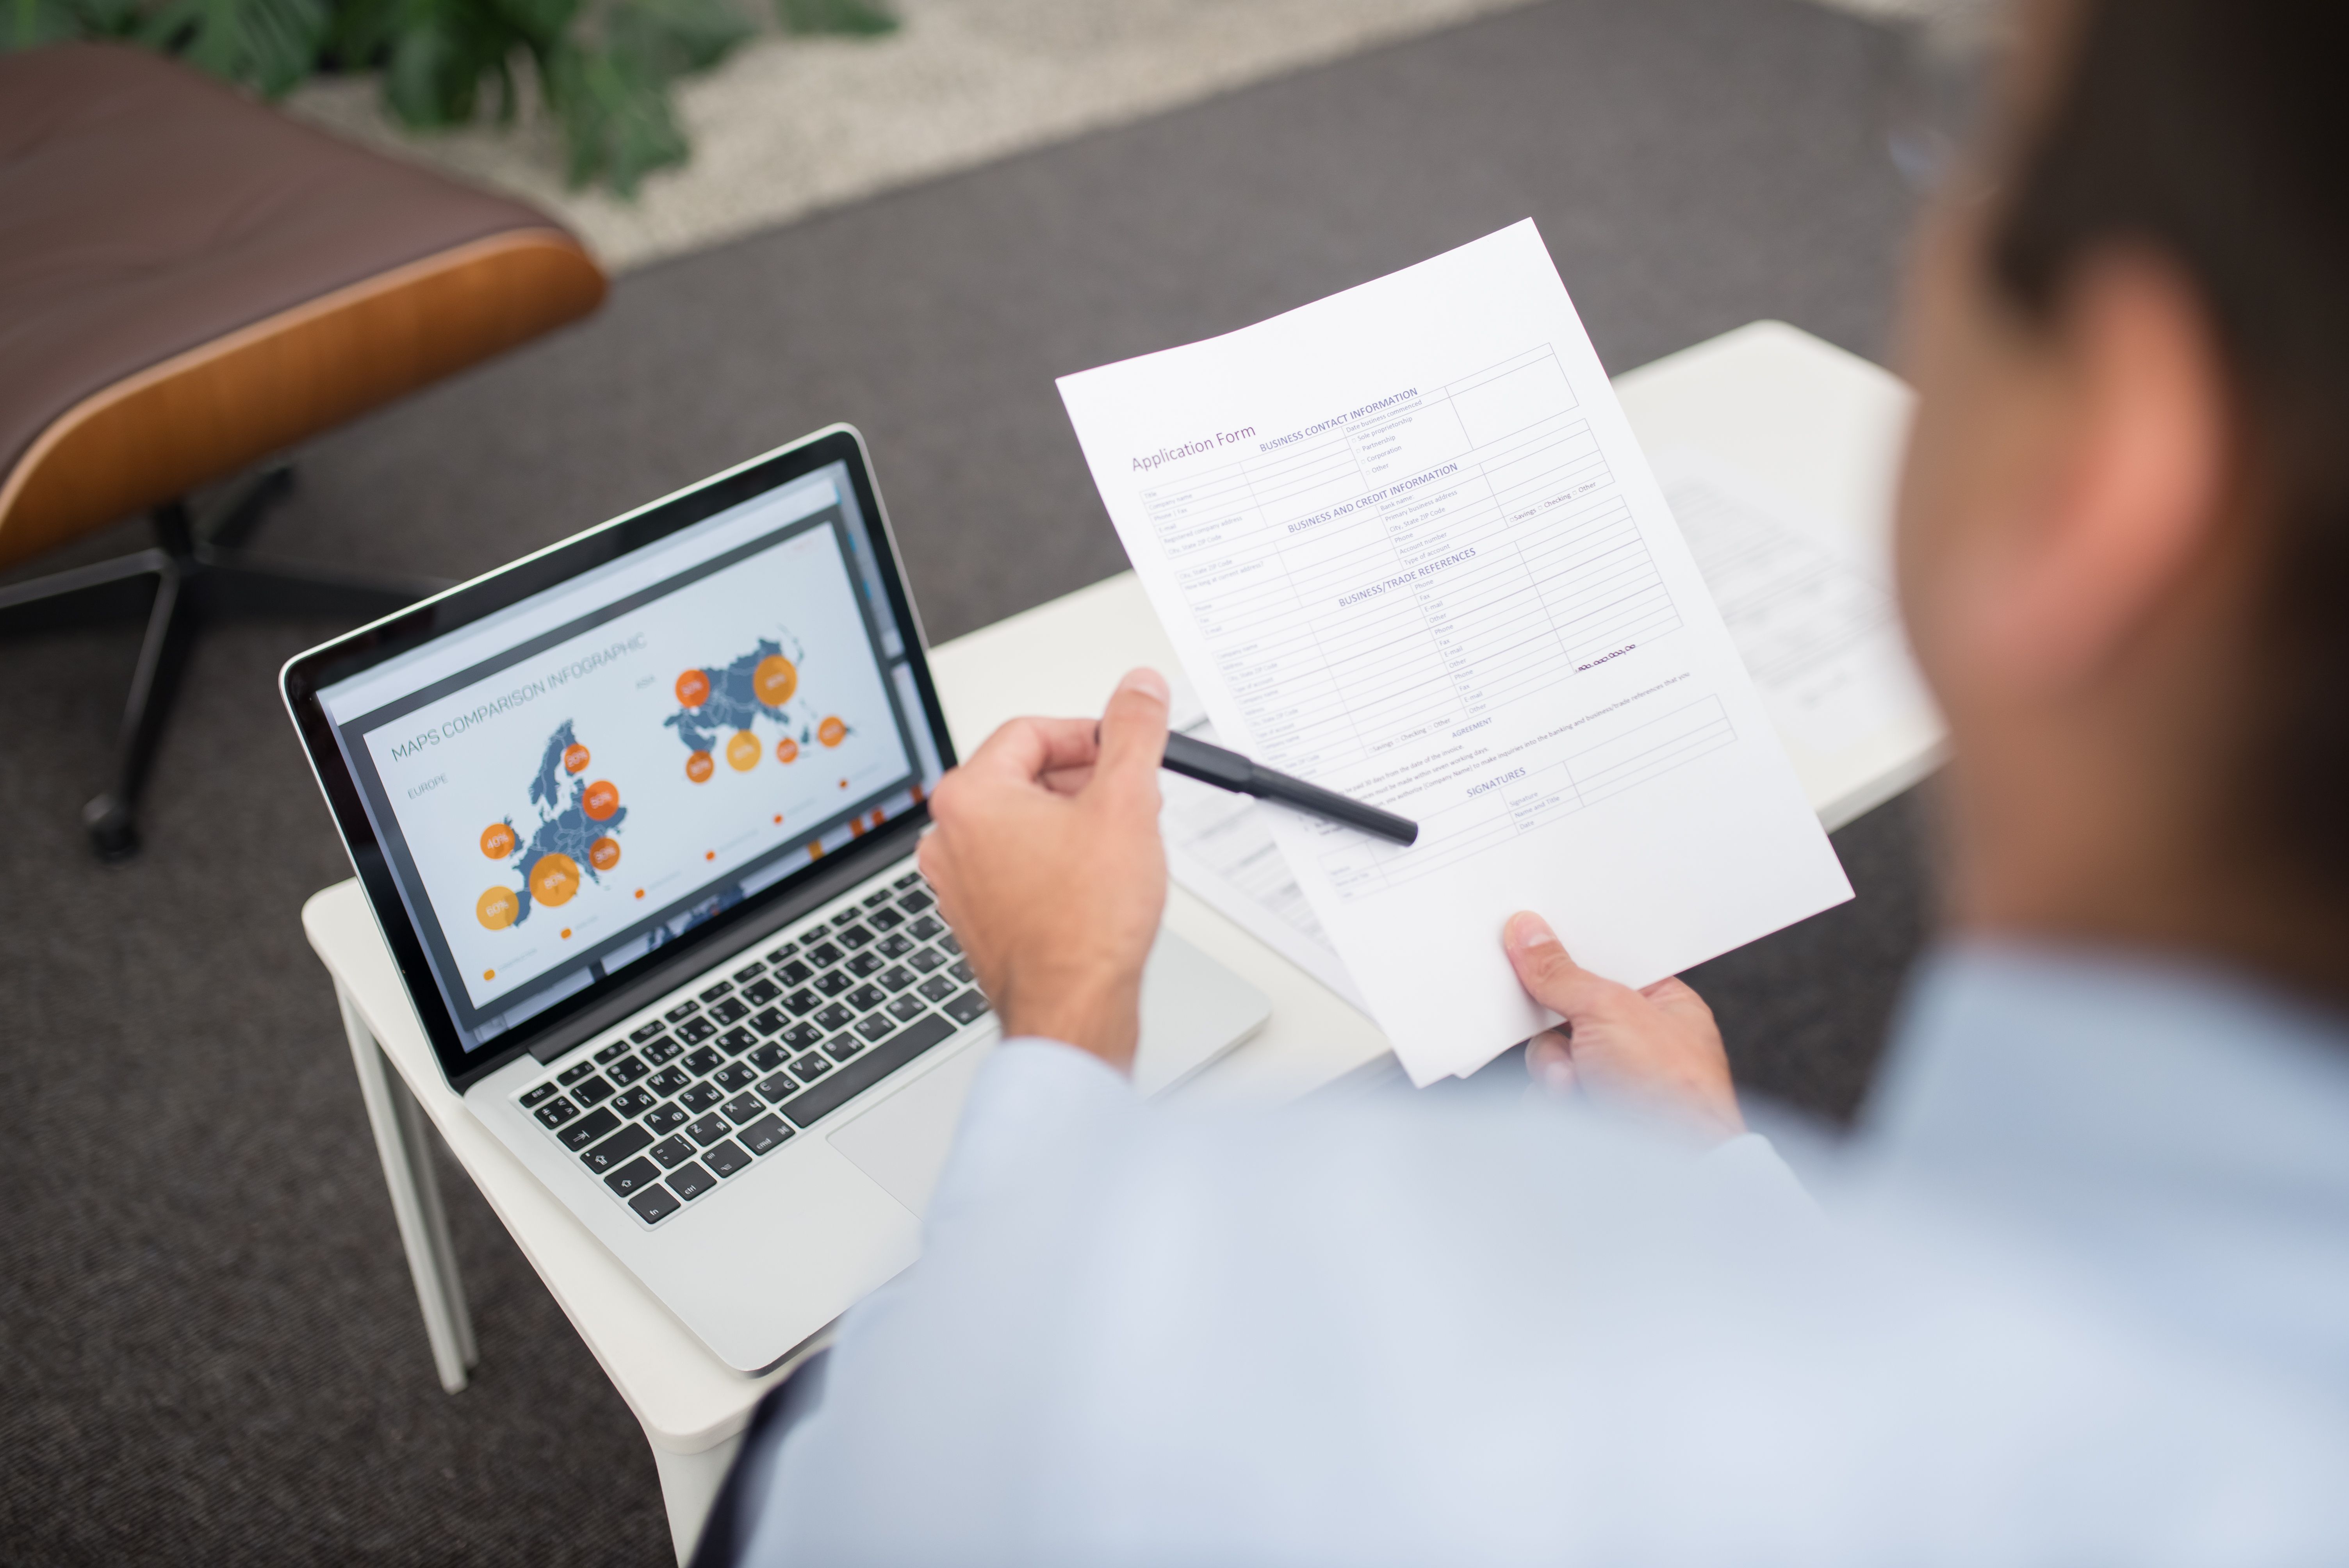
Enterprises across finance, legal, and shipping drown under mountains of unstructured documents, including scanned receipts, PDF invoices, bills of lading, handwriting, and complex tax schedules. Conventional OCR systems crumble when layouts drift or text is skewed, resulting in endless manual data keying, costly transcription errors, and days of verification backlog.
Organizations required an enterprise-grade extraction engine capable of handling messy, multi-column tables, handwritten signatures, and non-standard forms with near-zero latency and deterministic schema validation.
Our Engineering Solution
NemX built the Intelligent Document Extraction Engine: a multi-modal vision-language pipeline that combines LayoutLM spatial document understanding with specialized Vision-LLM parsers.
The engine ingests multi-format files, rectifies skew and noise automatically, and outputs strictly structured, Pydantic-validated JSON ready for direct ERP injection. Built-in confidence scoring flags borderline characters for rapid human review before ledger commit.
 Automated multi-page table and nested line-item extraction
- Vision-language semantic parsing of non-standard layouts
- Strict Pydantic JSON schema compliance and validation
- Instant human-in-the-loop review for low-confidence fields
- Sub-second extraction per document page via async workers
- SOC2 and GDPR-compliant processing with zero data retention
Multi-Modal Vision Pipeline
Unlike simple template OCR that breaks when a logo moves, our architecture treats each page as a multimodal visual graph, comprehending geometric coordinates, headers, checkboxes, and currency columns simultaneously.

Layout-agnostic token bounding box comprehension

Automated table grid alignment and multi-row summation

Asynchronous REST & Webhook APIs for bulk queue ingestion
The Business Impact
Enterprises integrating the engine eliminate clerical bottlenecks overnight, accelerating accounts payable cycle times, freight customs clearance, and loan origination approvals.

88% reduction in manual document transcription time

Near-zero data entry errors across invoice matching pipelines

Same-day financial invoice reconciliation across 50+ languages
Operational Velocity & Data Accuracy
The Intelligent Document Extraction Engine turns slow, manual paperwork into automated, validated data pipelines. By combining layout-aware vision models with rigorous validation rules, enterprises unlock straight-through processing, eliminate data entry fatigue, and accelerate operational cash cycles.
Key Takeaway: Eliminating manual invoice and contract keying freed hundreds of operational hours monthly while cutting intake-to-approval times from 5 days to 12 minutes.
Processing Time Reduction
Complex multi-page documents parsed, structured, and validated in under 3 seconds per file.
Field Extraction Precision
Sub-millimeter bounding box spatial models accurately capture line items, tax IDs, and dates.
Throughput Capacity
Async workers effortlessly scale to process hundreds of thousands of daily document pages.
Complex Grid & Line-Item Parsing
Reliably handles borderless tables, multi-line descriptions, and cross-column currency math without losing row-level alignment.
Dynamic JSON Schema Enforcement
Enforces strict data types, formatting rules, and mathematical validation so downstream SAP and Salesforce ERPs never choke on bad data.
Air-Gapped & VPC Deployments
Deployed inside customer cloud tenancies with optional on-prem GPU inference to satisfy government and banking confidentiality regulations.